
Follows What a Stranger Can Recall. That post was about whether your AI’s memory is real. This one is about whether its word is. It took one afternoon to build, and you can copy the idea with any assistant tonight, even without the code.
Every AI says “done”
Ask an assistant to fix something and it comes back with “Done.” Ask it to deploy, send, rename, clean up, and you get the same cheerful word. Sometimes it is true. Sometimes the thing is half-finished, or finished wrong, and you find out on Thursday. The word costs the AI nothing, so it says it every time.
People have two ways of coping. Either you check every single thing yourself, which means the assistant saved you no time, or you let it run and get burned now and then. Neither is how we treat a person. A person who says “done” and is wrong loses something: a little of your trust, and with it a little of their freedom to act without asking. Over months you learn exactly how much rope each colleague has earned.
So I gave my assistant the same deal.
Bet before you say it
My assistant now starts with a score of 100. Before it calls anything done, fixed or released, it has to bet part of that score that the claim is true. It says how sure it is, and that sets the size of the bet. Then someone settles the bet from evidence anyone could open: a file, a web page, a log line. Not the assistant’s own say-so.
The rules are deliberately lopsided. A wrong bet costs the whole stake. A right bet pays back about a tenth of it. That is how it should be: being right is the job, being confidently wrong is the expensive part. A bet nobody settles by its deadline counts as lost, so “done” can’t just quietly expire.
And the score does something. It sets how much the assistant may do on its own:
| Score | What it means |
|---|---|
| 80 and above | Works as usual. |
| 50 to 79 | Asks me before anything that cannot be undone. |
| Under 50 | I check every claim it makes. |
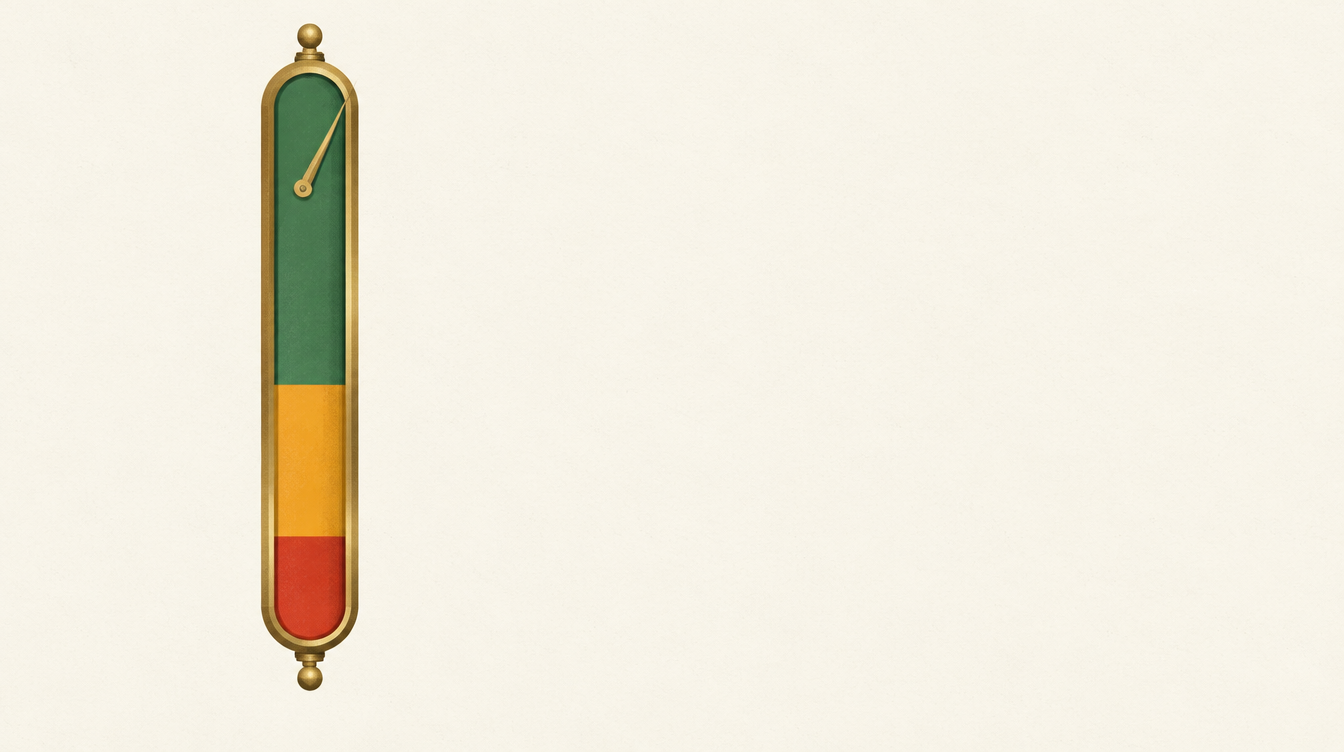
The score is never stored as a number anywhere. It is recomputed every time from the list of bets and settlements, which is just an append-only record. Nobody, including the assistant, can edit the score. They can only place the next bet.
What happened on day one
The assistant that helps me build things placed three bets today and lost two. It bet that a memory-trimming trick it had designed would work; a hidden test said no. It bet that a combined version of two tricks would carry both; wrong again. It won one bet about a result it had already measured twice. Score at the end of the day: 87. Still in the “works as usual” band, but twenty points closer to having to ask.
What I liked was watching the sizes of the bets. When I let it choose how sure it was, it put 35 points on the thing it had measured and 11 on the thing it was guessing at. The losses hurt where the guessing was. That is the whole mechanism: the stake makes the AI tell you, in a number, how much of its “done” is knowledge and how much is hope.
Meanwhile the assistant on my desk, the one I talk to by voice, started its own record this afternoon: one bet on a small checkable claim, staked 41 of 100 at 90 percent sure, settled won, score 104. One bet proves nothing. The record is what matters, and it is now being kept.
Why I think people will want this
Because it answers the question everyone asks about AI agents and nobody can answer today: how much should I let it do alone? The honest answer is “it depends on its track record,” and until now there wasn’t one. Every conversation started from zero. A score that survives between conversations, that only goes up when claims survive checking, is the missing piece between “approve everything” and “hope for the best.”
It also makes the assistant better at saying “I’m not sure.” Under these rules, a claim it is less than half sure of is refused outright: you can’t bet against yourself. So instead of a confident “done” you get “unverified,” which is the word you actually wanted.
Try it tonight, with or without the code
- Without any code: add one line to your assistant’s instructions: “Before you say done, state how sure you are from 50 to 100 percent, and what I could check to confirm it.” Keep a note with two columns, said and true. After a week you will know its real number, and so will it.
- With the code: the whole thing is one file you drop into a local assistant host I use called the Brainstem. It is on the public shelf at kody-w.github.io/RAR/stacks/trust-gate, marked staging because it is one day old. The rules it follows are written down as a small open protocol, rapp-trust/1, so anyone can keep the same kind of record in their own tools.
- Settle honestly. The record is only worth what the settlements are worth. If you let “done” slide, the score will lie to you later.
What this does not show yet: whether the assistant’s confidence gets better over weeks, and whether a score like this holds up when more than one person is settling bets. I have a bet open on that too: that at least one stranger installs it and settles a bet of their own within a week. If I lose, you’ll read it here.